

Maximum of 25 job preferences reached.
Top Remote Senior Site Reliability Engineer Jobs in Denver & Boulder, CO
Reposted 27 Days AgoSaved
Other • Social Impact
As a Senior Site Reliability Engineer, you will design, develop, and maintain reliable infrastructure for Wikimedia's API services, ensuring performance and availability while driving reliability engineering practices and improving developer experience.
Top Skills:
AnsibleArgocdAWSAzureGCPGitlabGoKubernetesOpentelemetryPrometheusPythonTerraform

Healthtech • Software
Design, automate, and maintain scalable infrastructure and SRE tooling. Manage Kubernetes clusters, CI/CD, monitoring, and incident response. Improve processes, reduce toil via automation, and collaborate with engineering and data teams to support domestic and international workloads.
Top Skills:
AWSAzureContainerdDnsDockerFirewallsGCPGoGrpcHelmKubernetesLinuxLoad BalancingPrometheusPythonRoutingShell ScriptingTcp/IpUdp
Healthtech • Social Impact • Software
Own the operational lifecycle of cloud-native data infrastructure: design and automate reliable deployments, observability, incident response, SLIs/SLOs, autoscaling and IaC, and improve platform efficiency and data freshness across GKE and Cloud Run.
Top Skills:
BashBigQueryCloud BuildCloud MonitoringCloud RunDatadogDockerGCPGithub ActionsGkeGoGrafanaJIRAKubernetesPrometheusPulumiPythonSentrySlackSnykSonarqubeTerraform

Software • Consulting
Lead 24x7 application support for external web applications: manage incidents, perform RCA, implement preventative fixes, build monitoring/alerts, expand Splunk functionality, create dashboards, collaborate with development and platform teams, and participate in on-call rotation.
Top Skills:
ApmAppdynamicsAWSDatadogGrafanaKubernetesLinuxMulesoftOpenshiftOpentelemetryPostmanPythonRumSeleniumServicenowShell ScriptingSplunk (Spl)Splunk CloudSplunk Observability CloudSplunk Synthetics

Software
Own and improve platform performance, reliability, and deployment automation. Manage cloud infrastructure, implement IaC, monitor systems with observability tools, provide operational support for distributed applications, and integrate production learnings into development workflows.
Top Skills:
Aiops ToolingAws Elastic ContainersAws RdsAws S3Claude CodeClaude CoworkDatadogHarness EngineeringInfrastructure As CodeKubernetesLlmsPrompt EngineeringRigorSplunk
Legal Tech • Software
Design and improve observability (monitoring, logging, tracing, SLIs/SLOs), build automation and CI/CD, lead incident response and reliability improvements, mentor SREs, run on-call, and apply AI/ML to operational signals to forecast and reduce risks.
Top Skills:
AWSBashCi/CdDistributed TracingGoInfrastructure As CodeKubernetesLoggingMonitoringPythonSlisSlos
Fintech • Real Estate • Software
Lead reliability and observability efforts across the org: design and maintain Kubernetes and AWS infrastructure, build CI/CD pipelines, drive IaC standards (Terraform/Crossplane), partner with 16+ teams to roll out tools and processes, participate in on-call rotation and incident response, and use AI tools to accelerate work.
Top Skills:
Ai ToolsArgoAurora PostgresAWSCi/Cd PipelinesCrossplaneDatadogDocumentdb (Mongo)EcsEksGithub ActionsHelmKubernetesMongoDBPostgresRdsTerraform

Software • Financial Services
Own day-to-day AWS and database operations for a serverless production platform, manage backups and disaster recovery, monitor and debug production, lead incident response and on-call, maintain infrastructure-as-code (SST/Pulumi), optimize costs, and mentor the team on operational best practices.
Top Skills:
AWSBashCloudwatchDnsDockerEventbridgeGithub ActionsLambdaLinuxPostgresPulumiPythonS3SqsSstTerraformTlsTypescript
3D Printing • Artificial Intelligence • Software • Design
Lead design and operation of scalable, multi-tenant spatial streaming platforms. Build Terraform-based cloud infrastructure, optimize CDN/content delivery, implement observability (SLI/SLO), run incident response/on-call, conduct post-mortems, enforce compliance and security practices, and mentor DevOps engineers to improve reliability and production readiness.
Top Skills:
Aws FargateCdnCoreweaveGrafanaKubernetesPrometheusTerraform
Logistics • Software
Own and operate scalable infrastructure on GCP (GKE, Cloud Run, AlloyDB); author Terraform modules; manage containerized workloads; build observability in Datadog; design CI/CD in GitHub Actions; automate operational workflows; lead incident response and post-mortems; partner with engineers to improve reliability, cost, and automation.
Top Skills:
AlloydbClickhouseCloud RunCloudflare WorkersDatadogDockerGCPGithub ActionsGkeGoGrafanaIamKafkaKubernetesNetworkingPostgresPrometheusPub/SubPythonRedisRedpandaTerraformTypescript
Insurance
Lead reliability and observability for the financial data platform: define SLOs/SLIs, build metrics pipelines, extend instrumentation across Velocity, Redpanda, MuleSoft, Snowflake, Fabric, and AWS; implement incident management (Datadog -> Incident.io -> ServiceNow), scale automation and remediation, and design AI-assisted SRE agents using Cursor for triage and root-cause analysis.
Top Skills:
Ai Coding AssistantsAWSCursorD365DatadogFabricGrafanaIncident.IoKafkaLlmsMulesoftOpentelemetryPower AppsPrometheusRedpandaServicenowSnowflakeVelocity
Other • Social Impact
The Senior Site Reliability Engineer is responsible for maintaining Wikimedia's infrastructure, improving reliability, automating processes, and collaborating with teams. The role involves troubleshooting, managing deployments, and leading incident responses while working remotely.
Top Skills:
AnsibleBashCassandraDebianGoGrafanaHhvmKubernetesMariadbMemcachedPHPPrometheusPuppetPythonRedisRubyShell
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free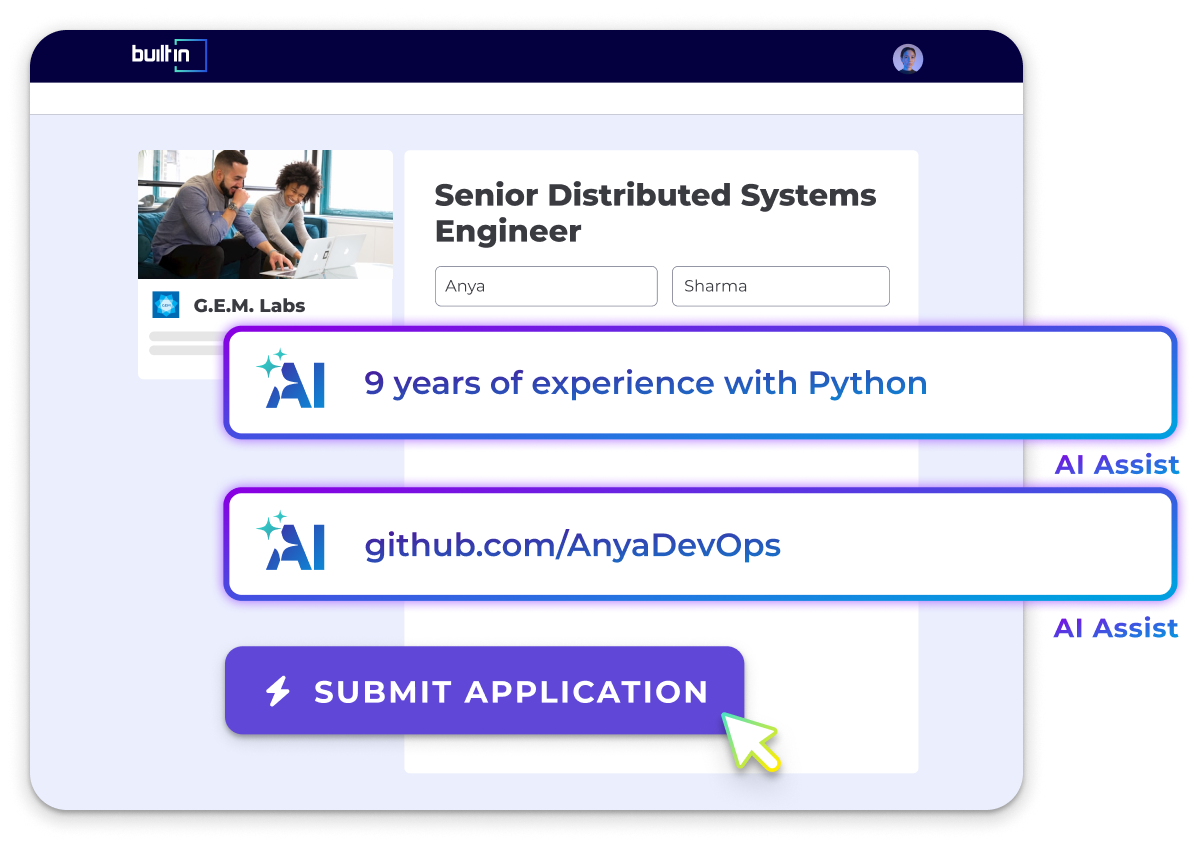

Information Technology • Security • Cybersecurity
Design, build, and scale Kubernetes-based, multi-tenant infrastructure and CI/CD systems. Own AI tooling infrastructure (MCP servers) and secure AI access patterns. Optimize CI/CD, streaming analytics (Kafka, Flink, ClickHouse), observability, and incident response. Implement IaC (Terraform, Helm, Pulumi), GitOps (Argo CD), progressive delivery, automated testing, and mentor engineering teams.
Top Skills:
Ai AgentsAi/Llm ToolingAksArgo CdBashClickhouseDatadogEksFlinkGithub ActionsGitlab CiGitopsGkeGoGrafanaHelmJenkinsKafkaKubernetesLangfuseLangsmithMcp ServersMlopsOpentelemetryPrometheusPulumiPythonTerraform

Reposted One Month AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
The Senior Site Reliability Engineer will lead security design and implementation for cloud infrastructures, mentor teams, and automate security solutions.
Top Skills:
AnsibleAWSAzureCloud Security ToolsCloudFormationGCPGoTerraform

Software
Support and improve production SaaS infrastructure across AWS, colocation, and hosted platforms. Administer Windows and Linux systems, virtualization, storage, networking, and database support. Lead incident troubleshooting, root cause analysis, monitoring improvements, vulnerability remediation, automation initiatives, and medium-sized infrastructure projects. Collaborate on compliance (SOX/PCI/HIPAA), disaster recovery, and documentation to increase operational reliability.
Top Skills:
AWSBackup And RecoveryBashDatabasesFirewallsLinuxMonitoring PlatformsNetworkingPowershellPythonStorage SystemsVirtualizationWindows Server
Software • Financial Services
Lead reliability, observability, and resilience for cloud-based financial SaaS. Define SLOs/SLIs, design monitoring/tracing, own incident response and runbooks, build IaC and automation, implement AIOps, perform chaos and load testing, and write production-grade Python tooling while ensuring security and compliance.
Top Skills:
AnsibleAWSAzureBashCi/CdCloudFormationDatadogElkGitGrafanaNew RelicPowershellPrometheusPythonTerraform

Big Data
You will manage AWS infrastructure, automate deployments, debug application issues, and improve the operational health of Metabase Cloud.
Top Skills:
AWSDatadogGoGrafanaKubernetesPrometheusPythonTerraform

Real Estate • Financial Services • PropTech
Lead AWS-based SRE activities for products migrated from on-prem: ensure reliability, observability, automation, CI/CD (GitOps), Kubernetes/EKS operations, Terraform IAC, database/RDS administration, networking and security, and collaborate with development and platform teams to optimize SaaS operations.
Top Skills:
AmiArgocdAWSAws Elastic BeanstalkAws Transfer FamilyAws Well-Architected FrameworkAzure DevopsBashCloudwatchCurlDockerEc2EksFluxcdGitGitopsHTTPIstioKubernetesLinkerdLoad Balancer (Elb/Alb)PowershellPythonRdsService MeshSQLTerraformWget
Cloud • Security • Software • Cybersecurity
Build and run Gov/Sovereign cloud SRE for Veeam Data Cloud: document platform, define SLIs/SLOs, run incident response, close observability gaps, design resilient Azure infrastructure, automate IaC/CI/CD pipelines, support on-call, and collaborate with security/compliance teams to operationalize reliability.
Top Skills:
Application InsightsArgocdAws CloudformationAzureAzure Api ManagementAzure Arm TemplatesAzure DevopsAzure FunctionsAzure MonitorAzure StorageBitbucketC#Cosmos DbDaggerElastic StackElkEntra IdFluxcdGitGithub ActionsGitlab CiGoGrafanaJavaJavaScriptKubernetesMicrosoft TfsOpentelemetryPrometheusPulumiServerless FrameworkTerraformTerragruntTypescript
Cloud • Security • Software • Cybersecurity
Lead reliability and performance efforts for distributed metadata systems: tune and optimize systems, develop monitoring and automation, manage rollouts, troubleshoot incidents, run simulations and analytics, and support database/configuration management to improve global network stability and capacity.
Top Skills:
Big DataLinuxPostgresPythonSQLUnix
Cloud • Security • Software • Cybersecurity
Lead reliability, scalability, and observability for high-density AI hardware infrastructure. Build Python automation and IaC, design telemetry and Prometheus/Grafana dashboards, implement AI-assisted tooling and anomaly detection, manage 24x7 on-call incident response, and coordinate vendor field operations to ensure uptime.
Top Skills:
Bare-MetalBgpGrafanaInfrastructure-As-CodeIpv4Ipv6LlmsLokiOpentelemetryPagerdutyPrivate CloudPrometheusPythonRest ApisSlackTimeseries Databases
Software
Design, implement, and operate observability and reliability for cloud platforms. Measure and monitor production systems, reduce toil via automation, drive incident response and on-call practices, and partner with product and platform teams to improve scalability, resiliency, and observability.
Top Skills:
AnsibleAWSAzureBlamelessCloud SdksCloudwatchContainersCriblFirehydrantGrafanaJavaScriptKibanaKubernetesLinuxNew RelicNode.jsPagerdutyPrometheusSentrySplunkTerraformTypescript
Artificial Intelligence • Software
As a Software Engineer in Reliability, you'll architect and manage multi-cloud GPU infrastructure, ensuring performance, security, and scale while debugging complex hardware/software issues.
Top Skills:
AmdAWSBashGoGpuInfinibandLinuxNvidiaOciPythonRdma
Software • Cybersecurity
This role involves managing Kubernetes clusters, cloud infrastructure, and CI/CD pipelines. The engineer will enhance system reliability and efficiency while troubleshooting production issues.
Top Skills:
AlertmanagerAWSAzureBashCi/CdDockerElastic StackElasticsearchGCPGoGrafanaHelmKafkaKubernetesLokiMongoDBOciPrometheusPythonRedisSparkTerraform
Software
The role involves managing compute infrastructure for decentralized applications, requiring critical thinking, documentation skills, and experience in Kubernetes and blockchain management.
Top Skills:
BlockchainGitopsInfrastructure-As-CodeKubernetesProgramming Languages

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Denver & Boulder, CO Companies Hiring Remote Senior Site Reliability Engineers
See All






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
