

Maximum of 25 job preferences reached.
Top Remote Senior Site Reliability Engineer Jobs in Denver & Boulder, CO

Big Data • Healthtech • HR Tech • Machine Learning • Software • Telehealth • Big Data Analytics
Own the reliability, performance, resilience, observability, and security of AWS and Kubernetes infrastructure supporting products and AI/ML workloads. Define SLOs, lead incident response and root-cause analysis, build Terraform automation, optimize cloud costs, reduce operational toil, and establish deployment standards that help engineers ship reliably. Participate in on-call rotations and maintain HIPAA-compliant infrastructure.
Top Skills:
AWSClaudeDatadogGitlabGoHipaaIstioKubernetesNatsPostgresPythonSoc 2TerraformTypescript
Reposted 22 Days AgoSaved
Software • Defense
Work as an SRE embedded with product teams to improve reliability by fixing application code (primarily TypeScript), building observability (Prometheus, Loki, Grafana, Alloy), defining SLIs/SLOs, leading incident response and postmortems, automating toil, and supporting deployments across on‑prem DoD and AWS environments.
Top Skills:
AlloyAWSBashContainersDockerGithub ActionsGitlab Ci/CdGoGrafanaJenkinsKubectlKubernetesLokiNode.jsPrometheusPythonTypescript

Reposted 25 Days AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
Develop and maintain Kubernetes runtime environments, support developers, resolve critical issues, and participate in on-call rotations for production systems.
Top Skills:
AWSAzureCert-ManagerCorednsCrdsCriCsiGatekeeperGCPGoHelmKubernetesKustomizeOperatorsPythonTerraform
6 Days AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Build and operate reliable, scalable production infrastructure for GitLab’s user-facing services. Responsibilities include developing infrastructure automation and tooling, managing Kubernetes deployments, maintaining infrastructure as code, supporting CI/CD and GitOps, participating in on-call and incident response, improving observability and SLOs, troubleshooting production systems, and documenting operational practices. The role spans Intermediate through Senior Staff levels and requires strong software engineering, cloud, reliability, and asynchronous collaboration skills.
Top Skills:
AlertingAWSCi/CdGCPGitopsGoInfrastructure As CodeKubernetesLoggingMetricsRubySlisSlosTerraform
Cloud • Security • Software • Cybersecurity
Deploy and operate scalable, highly available cloud systems; improve application, network, and infrastructure reliability, security, performance, and capacity; automate cloud deployments; monitor services and SLAs; analyze logs and events; troubleshoot infrastructure issues; and provide operational recommendations for large-scale cloud platforms.
Top Skills:
Amazon Ec2Amazon Web Services (Aws)AnsibleAws CloudwatchBashCi/CdContainerizationDockerGitGitlabHelmInfrastructure As Code (Iac)JenkinsKubernetesLog AnalysisMavenAzureNagiosOrchestrationPythonSplunkSvnVersion ControlVmware Vsphere
Big Data • Cloud • Software • Database
Seeking a Site Reliability Engineer with expertise in networking and distributed systems for building secure multi-cloud infrastructure. Responsibilities include maintaining network architecture and ensuring reliable service-to-service communication, involving a 24/7 on-call rotation.
Top Skills:
AWSAzureBgpDnsGCPIpv6KubernetesLoad BalancingMtlsService MeshTcp/IpTlsVpcsVpns

Cloud • Security
Own reliability, availability, performance, and capacity for production SaaS services across Azure, AWS, and a FedRAMP High environment. Build observability, SLOs, monitoring, infrastructure automation, and remediation workflows; lead incident response, postmortems, support escalations, and disaster recovery efforts. Manage Terraform, CI/CD, Kubernetes, WAF, networking, and observability costs while improving on-call operations and collaborating with Security, Product, Support, and Development.
Top Skills:
AksAWSAzureAzure App ServiceAzure DevopsAzure Front DoorAzure MonitorAzure Service BusAzure SqlAzure StorageAzure WafCloudflareCloudwatch Logs InsightsConsulDatadogElk StackFedrampImpervaIso 27001JenkinsJira Service ManagementJSONKubernetesMicrosoft Entra IdNist 800-53OidcPagerdutyPciPowershellPythonRedisS3SaltstackSAMLSoc 2TerraformYaml

Edtech • HR Tech • Software
Lead reliability engineering for critical SaaS services by defining SLOs, managing major incidents, improving observability, architecting scalable infrastructure, advancing deployment safety, and mentoring engineers. The role partners with engineering and product leaders to balance feature delivery with system resilience, while driving reliability standards, automation, and recruiting across the SRE organization.
Top Skills:
AWSContainer OrchestrationInfrastructure As Code

Artificial Intelligence • Software • Conversational AI • Automation
Build and improve Replicant’s AI-native platform, including site reliability, CI/CD, developer tooling, observability, incident management, cloud infrastructure, and autonomous-agent harnesses. Own production infrastructure reliability at scale, reduce operational toil, improve deployment workflows, participate in on-call rotation, and shape platform engineering patterns. The role uses TypeScript/Node.js, Python, Terraform, Kubernetes, Helm, GCP, and modern monitoring tools.
Top Skills:
ClaudeCursorDatadogFreeswitchGCPGitlab CiGrafanaHelmKubernetesLlmsNode.jsPrometheusPythonSipTerraformTypescript

Other
Build and improve Replicant’s AI-native platform infrastructure, including site reliability, CI/CD, developer tooling, observability, incident management, and agent harness systems. Own production infrastructure patterns, deployment workflows, and developer self-service across Kubernetes and cloud environments. Participate in on-call and incident response while improving scalability, availability, and operational efficiency for real-time conversational AI traffic.
Top Skills:
ClaudeCursorDatadogFreeswitchGCPGitlab CiGrafanaHelmKubernetesLlmsNode.jsPrometheusPythonSipTerraformTypescript

AdTech • Cloud • Digital Media • Information Technology • News + Entertainment • App development
Design, deploy, and maintain on-premises and cloud playout infrastructure for IP video distribution. Build automation, CI/CD pipelines, monitoring, and scalable fault-tolerant systems. Drive releases, troubleshoot broadcast incidents, mentor SREs, and provide 24/7 on-call support.
Top Skills:
AnsibleAWSAzureBashBroadcast TechnologiesCi/CdContainerizationGCPIp VideoJavaScriptKubernetesLinuxPerlPythonRubyStreamingTerraform

eCommerce • Fintech • Payments • Software
The role involves ensuring software reliability and performance, managing incidents, developing infrastructure automation, and mentoring junior engineers within a platform team.
Top Skills:
AWSCloudFormationDatadogKubernetesOpentelemetryRubyRuby On RailsTerraform
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free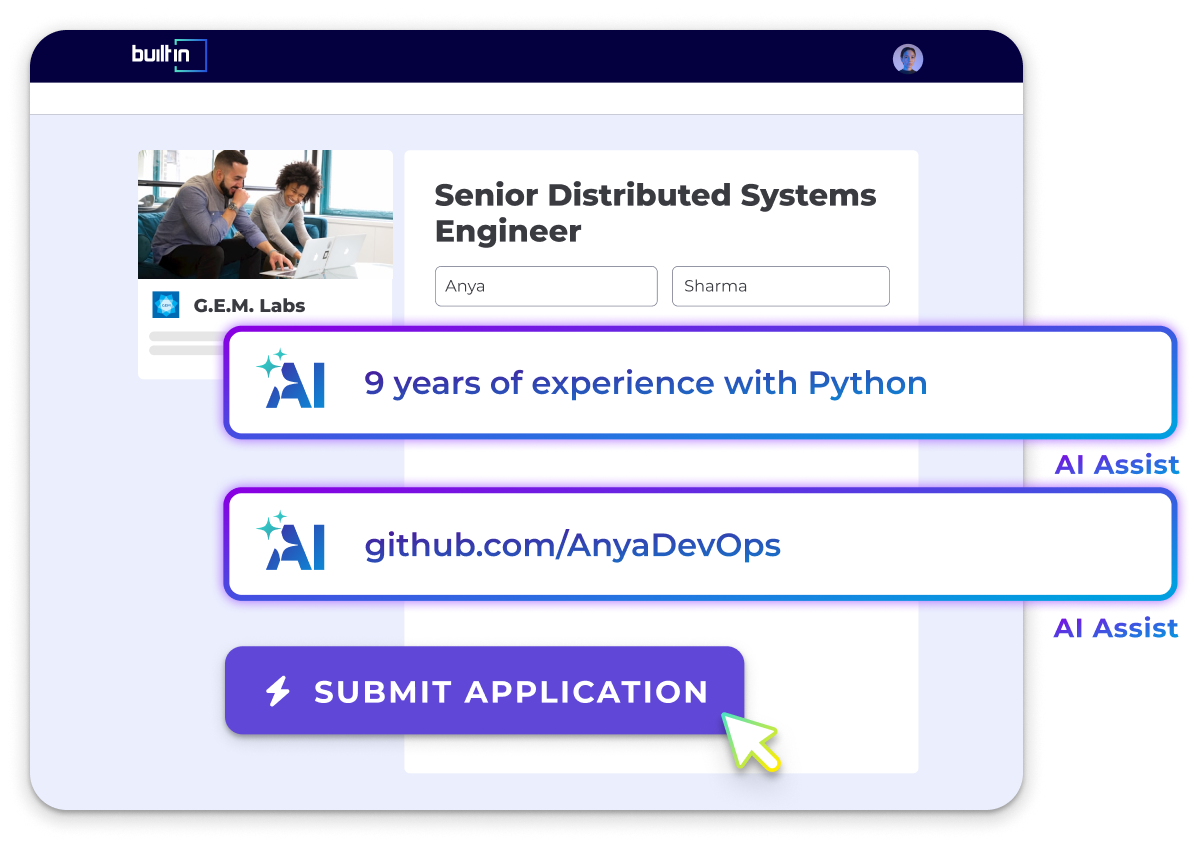

Agency • Cloud • Professional Services • Software
Improve AWS production infrastructure reliability, observability, performance, and operational maturity. Build Terraform infrastructure, enhance CI/CD, automate operational work, manage incident response and on-call operations, lead postmortems, improve application resilience, support capacity planning and database reliability, and collaborate on security hardening and compliance. Mentor engineers and promote reliability practices across the organization.
Top Skills:
AWSCi/CdCircleCIDatadogGithub ActionsGitlab CiLinuxNew RelicPostgresRubyRuby On RailsSlisSlosTerraform
Information Technology • Insurance • Software
Own and operate production services end-to-end to ensure reliability, scalability, performance, and operational health. Define SLIs/SLOs, perform incident response and root cause analysis, build automation and self-healing, manage production changes, and collaborate with engineering, product, and operations teams to improve system design and observability.
Top Skills:
.NetAWSC#Ci/CdInfrastructure As CodeJavaKubernetesLinuxPythonReactRelational DatabasesWindows

Edtech • Kids + Family • Sports
Audit infrastructure, deployment pipelines, monitoring, alerting, incident response, on-call practices, and internal tools. Produce actionable audit reports, implement code and configuration fixes, improve SLOs and reliability practices, advise on scalable architecture, and partner with engineers on implementation and handoff. The role is a fully remote, part-time consulting engagement with potential for full-time conversion.
Top Skills:
Ai Coding ToolsAWSCi/CdDatadogGrafanaPrometheus
Artificial Intelligence • Cloud • Fintech • Machine Learning • Mobile • Software
Lead design, development, deployment, and scaling of cloud infrastructure and SRE tooling. Build automation, CI/CD, observability, capacity planning, and reliability improvements; collaborate with product teams to define non-functional requirements and resolve production issues.
Top Skills:
.NetApi GatewayAWSAzureC#Data LakehouseDatabricks DeltaDatadogElasticsearchElkEvent HubsFunctions/ServerlessGitGrafanaJavaJenkinsKafkaKibanaKubernetesLogstashPowershellSnowflakeSqsTeamcityVisual Basic

Healthtech • Software
Manage and optimize a multi-account AWS environment supporting production healthcare applications and analytics platforms. Responsibilities include AWS infrastructure administration, CI/CD and infrastructure automation, observability, incident response, on-call support, disaster recovery validation, HIPAA/HiTrust compliance, IAM and security controls, and support for containerized Java and Python applications. The role also contributes to Kubernetes and EKS modernization initiatives and partners with developers to resolve complex production issues.
Top Skills:
Amazon EksApi GatewayArgocdAuroraAWSAws CloudformationAws CodepipelineAws Security HubBashCloudfrontCloudwatchCortex CloudDatadogDockerEc2EcsFargateGitGuarddutyHelmIamJavaJenkinsKubernetesLambdaLinuxPrismaPythonRdsS3Spring BootUbuntuZabbix

Cloud • Software
The Senior Site Reliability Engineer will automate operations using Python, manage Kubernetes and OpenStack clusters, and ensure high availability for enterprise infrastructures.
Top Skills:
KubernetesLinuxOpenstackPython

Gaming
Own and operate large-scale infrastructure for sports betting and media platforms across cloud and production environments. Lead infrastructure migrations, build Kubernetes platform tooling and CI/CD automation, improve observability and alerting, support development teams, and participate in incident response. The role requires strong distributed-systems expertise, production troubleshooting, cross-team project leadership, technical communication, and mentoring.
Top Skills:
ArgocdAWSBashCephCiliumDatadogGCPGithub ActionsGoHelmIstioKubernetesLinuxPgbouncerPostgresPythonTalos OsTerraform
Reposted 23 Days AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
As a Senior Site Reliability Engineer, you'll design and build complex systems, support Atlas platform operations, automate processes, and ensure high availability of services.
Top Skills:
AWSAzureDnsGCPGoHTTPLinuxPythonRubyTls

Information Technology • Security • Cybersecurity
Own production operations and highly available cloud infrastructure for regulated government environments. Lead incident response, root-cause analysis, disaster recovery testing, compliance operationalization, audit readiness, vulnerability management, and continuous monitoring. Build automation, secure CI/CD pipelines, infrastructure-as-code, observability, and compliance tooling across Kubernetes, Linux, containers, and cloud platforms. Partner with security, compliance, and engineering teams to improve reliability, deployment safety, and regulatory sustainment.
Top Skills:
Aws GovcloudBashCi/CdDod Il4Dod Il5FedrampGitopsGoGrafanaKubernetesLinuxNist 800-53PrometheusPythonStigTerraformUnixZero Trust

Cloud • Computer Vision • Information Technology • Sales • Security • Cybersecurity
Senior SRE owning availability, automation, and observability for CI/CD platform services. Build and operate infrastructure, run on-call, lead incident response, mentor engineers, drive design/capacity planning, integrate AI-assisted workflows, and improve cross-team reliability.
Top Skills:
Active DirectoryAnsibleApache AirflowSparkAWSAzureBashBazelBitbucketCassandraChefDatadogDnsFirewall RulesGCPGitGithub ActionsGitlabGitlab CiGoGrafanaHoneycombHumio/LogscaleJenkinsKafkaKubernetesLoad BalancersMongoDBMySQLNasNew RelicNfsObject StorageOpensearchOraclePostgresPowershellPrometheusPulsarPuppetPythonRabbitMQRedis/ValkeyRedpandaRoutingSaltSanSplunkTerraformVarnishVipsWindows Server

Artificial Intelligence • Cloud • Information Technology • Software
Design and operate large-scale GPU infrastructure for distributed AI training, ensuring reliability, performance, and efficient customer partnerships.
Top Skills:
AnsibleCudaDeepspeedFsdpGpuHelmInfinibandKubernetesLinuxMegatronNcclNvidia A100Nvidia B200Nvidia H100NvlinkPyTorchRoceTerraform
Reposted One Month AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
The Senior Site Reliability Engineer will develop and support distributed storage services, ensuring reliability and operational safety, with a focus on automation and efficiency.
Top Skills:
AWSAzureDnsGoGoogle Cloud PlatformKubernetesLinuxPythonTcp/IpTls

Artificial Intelligence • Information Technology • Software • Database
As a Site Reliability Engineer, you will design, implement, and maintain scalable infrastructure, ensure system reliability, automate processes, and collaborate with engineering teams.
Top Skills:
DockerElk StackGoGrafanaJavaKubernetesNode.jsPrometheusPulumiPythonRubyTerraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.





Popular Job Searches
All Filters
Total selected ()
No Results
No Results
